OpenJev-Fast

6× Faster Open‑Jev‑27B Inference with Specialized CUDA Kernels

Fused CUDA kernels, shared-prefix execution, tuned GEMMs, and CUDA Graphs on a single NVIDIA B300.

Yiqi Lyu
Northwestern University
Advised by Zhaoran Wang
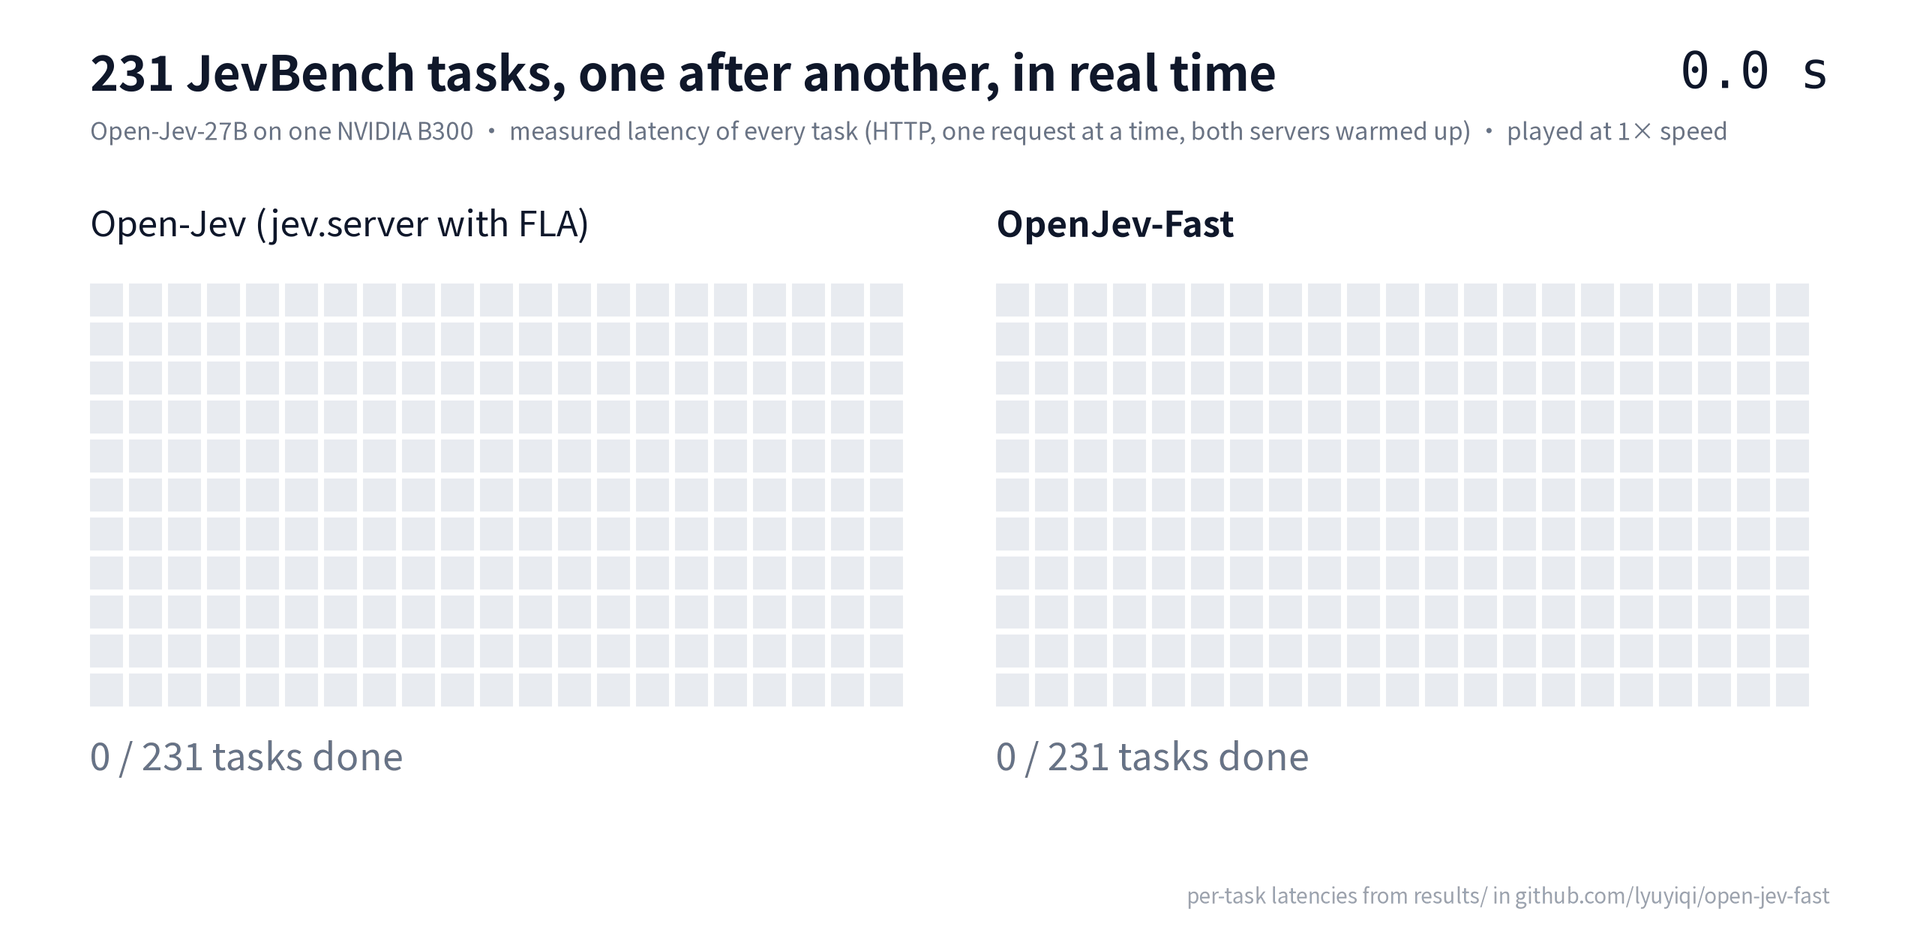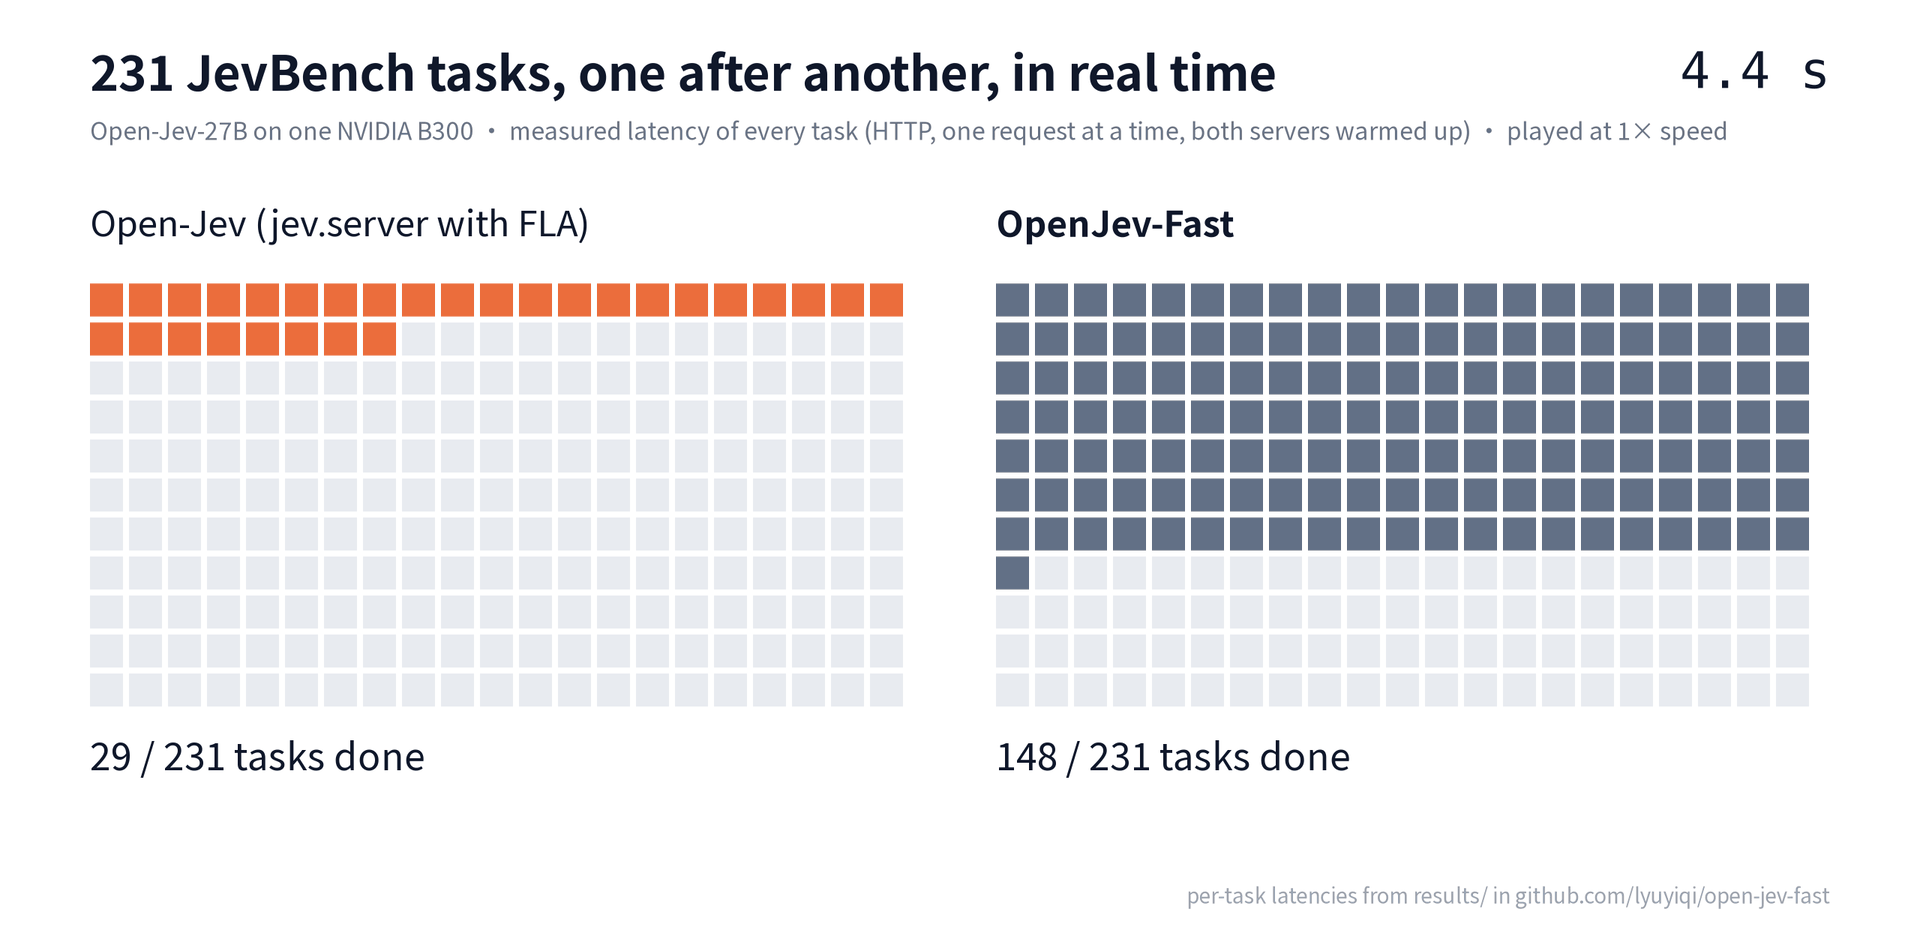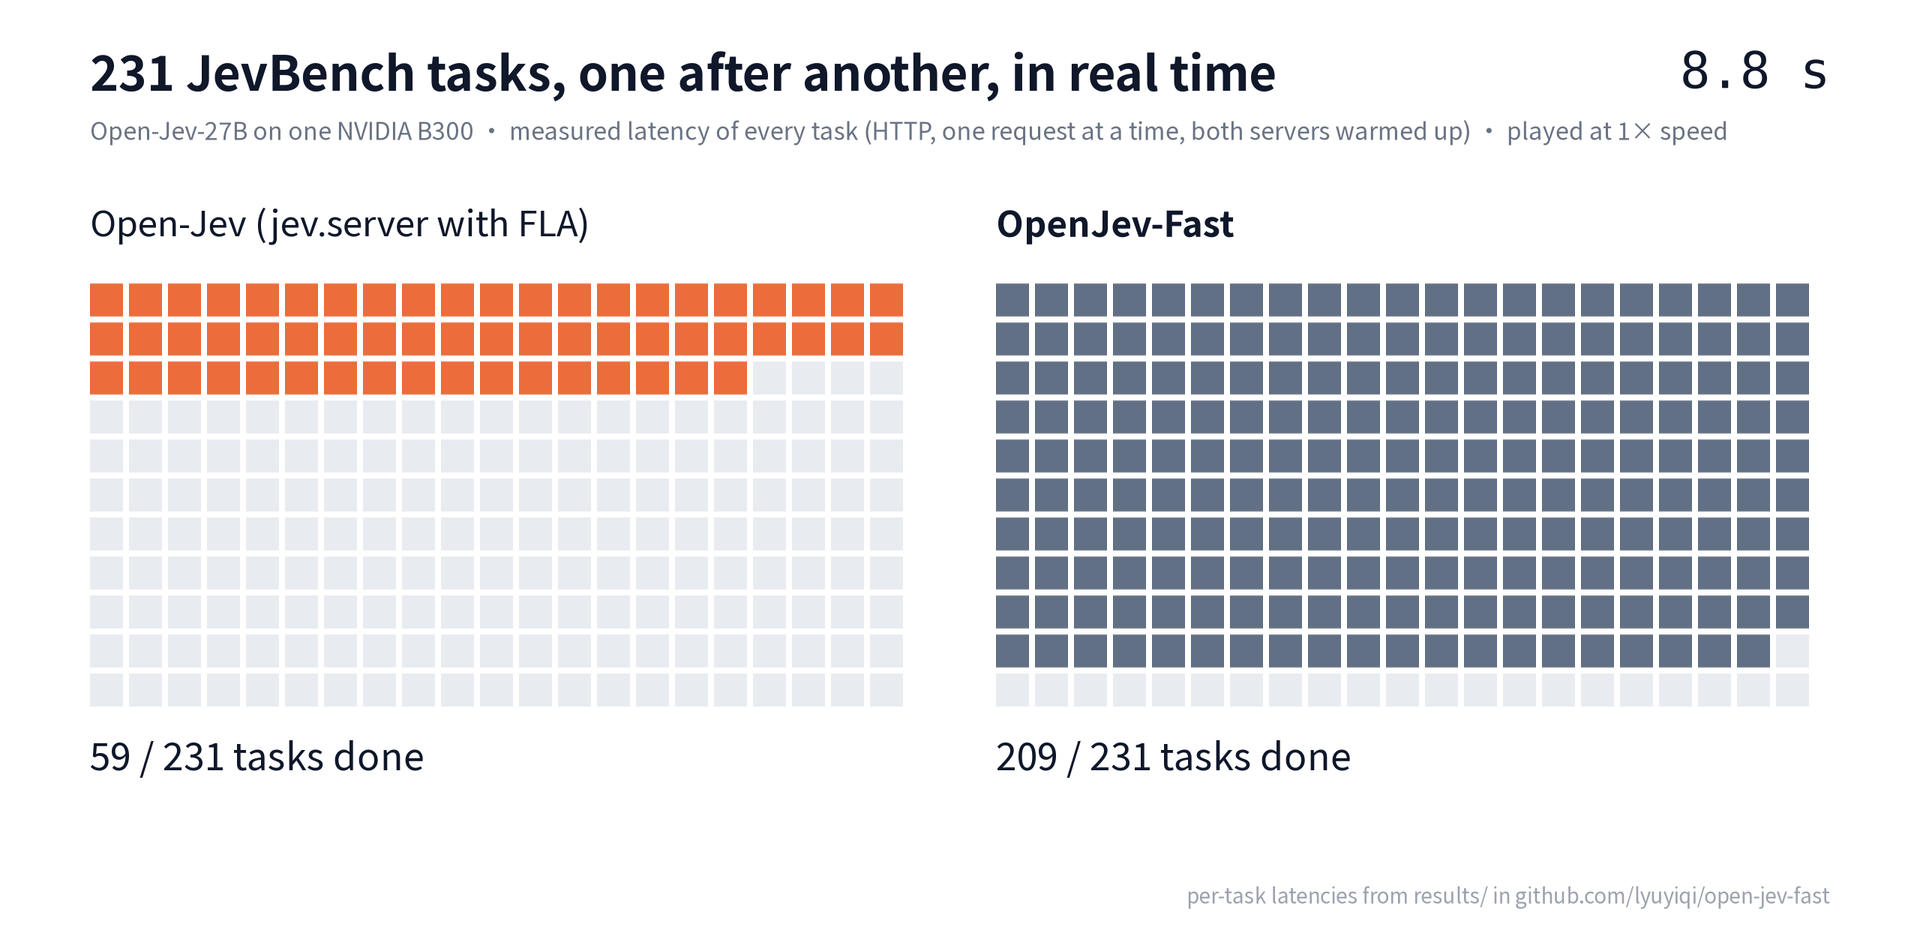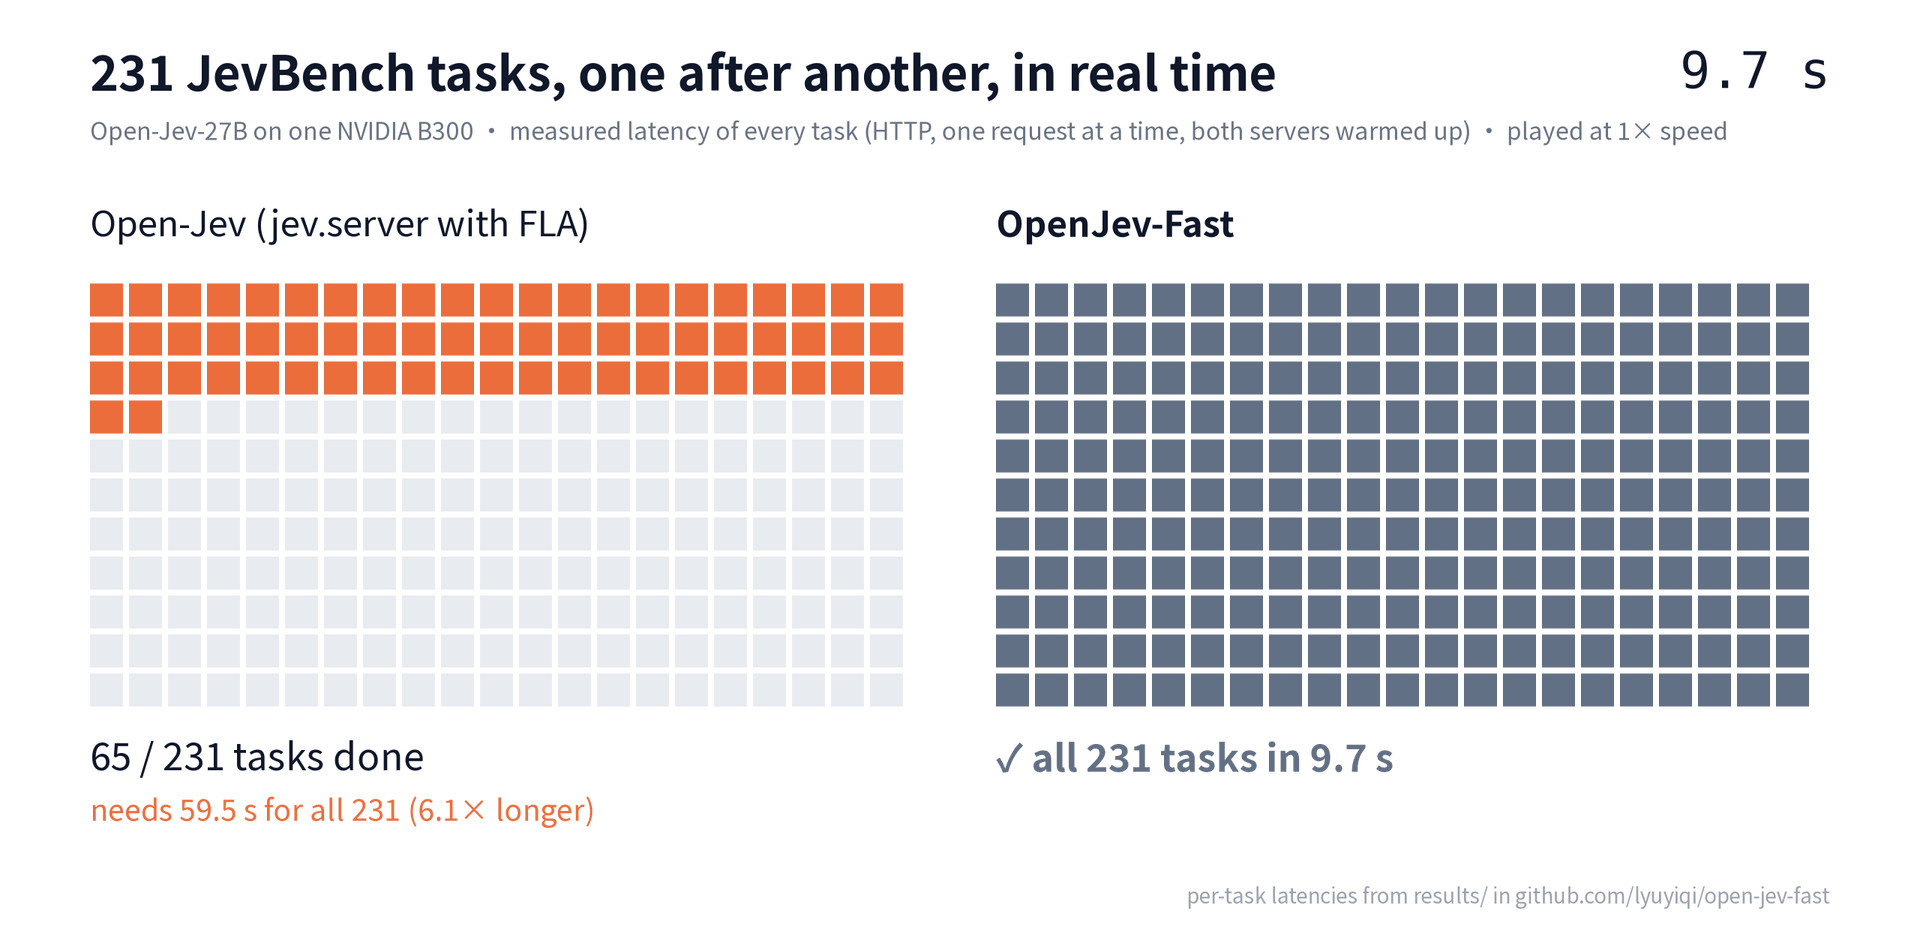
The 231 JevBench tasks sent one after another to each server, replayed in real time

The 231 public JevBench tasks sent one after another to each server on the same GPU, replayed at real speed from the measured per-task latencies (HTTP, both servers warmed up).

TL;DR

An inference backend for Open-Jev[1]. It runs locally, keeps the model and the request format of Open-Jev's local server, and replaces the forward pass with fused CUDA kernels, a prefix tree that computes shared prompt text once, and CUDA Graphs.

14.8×
256.0 → 17.3 ms
vs. default PyTorch path
6.0×
103.7 → 17.3 ms
vs. PyTorch + FLA kernels
6.1×
258 → 42 ms
JevBench mean latency, HTTP
197 / 231
original: 198 / 231
JevBench accuracy; one near-tie prediction changed

Step by step

Latency of one inference as optimizations are added

Example request: 3 questions, 7 candidates, 539 tokens. Median latency of the forward pass plus scoring head.

How it works

1

Fused CUDA kernels

Hand-written kernels replace every non-matmul op in a layer. Kernels per request drop from ~5000 to 642, and the CPU launch bottleneck goes away.

2

Two-level prefix tree

The shared context is computed once, each question once, and each candidate only its tail, all in one packed forward pass.

3

Gated DeltaNet and attention kernels

The linear-attention recurrence and the tree-masked attention run in our own kernels (mma.sync, ldmatrix, cp.async in inline PTX): 74 → 36.5 µs and 21.4 → 12.7 µs per layer.

4

Tuned GEMMs + CUDA Graphs

Merged weights, split-K with fp32 partial sums, per-shape cuBLASLt algorithms, and one CUDA Graph per request shape.

Two-level prefix tree for the example request

Prefix tree for the example request. Linear-attention layers still run each candidate over its full path, so results match the original; full-attention layers use an ancestor mask.

JevBench

Per-task latency distribution on JevBench

Cumulative share of the 231 public JevBench[11] tasks finished within a given latency, sent over HTTP to the local server, one request at a time, from the same machine. Both servers warmed up (second pass).

Original jev.server (with FLA)open-jev-fast
Accuracy198 / 231197 / 231
Mean latency258 ms42.0 ms
P50 / P95150 / 802 ms17.4 / 137 ms
Slowest task1.5 s0.21 s

Correctness

  • 98–100% of the element-wise kernels' outputs are bit-identical to the PyTorch/FLA reference; the Gated DeltaNet and attention kernels match FLA and cuDNN within bf16 rounding (relative L2 about 10⁻³).
  • On the example request, probabilities differ from the original by at most 0.0082 (the two original paths, with and without FLA, differ by 0.0087 from each other); on a 10,722-token request by 0.019. Decisions are unchanged.
  • On JevBench, accuracy changes by one task: one near-tie prediction changed (original: 0.504 vs 0.496).

Setup and limits

  • Latency is the forward pass plus scoring head for the example request, with prompts tokenized beforehand. All three numbers use the same script: median of 30 runs after 5 warm-ups.
  • Tested only on an NVIDIA B300. Needs about 98 GiB of GPU memory.
  • bf16 only; one request at a time; a new request shape adds 1–3 s once, for graph capture.

Full details, the step-by-step breakdown and failed attempts are in the README and report (PDF).

References
  1. Open-Jev contributors. Open-Jev. github.com/Zefan-Cai/Open-Jev, 2026.
  2. Open-Jev-27B-v1.1. huggingface.co/ZefanCai/Open-Jev-27B-v1.1.
  3. Qwen Team. Qwen3.8-27B. huggingface.co/Qwen/Qwen3.8-27B.
  4. S. Yang and Y. Zhang. FLA: A Triton-Based Library for Hardware-Efficient Implementations of Linear Attention Mechanism. github.com/fla-org/flash-linear-attention, 2024.
  5. S. Yang, J. Kautz and A. Hatamizadeh. Gated Delta Networks: Improving Mamba2 with Delta Rule. ICLR 2025. arXiv:2412.06464. S. Yang et al. Parallelizing Linear Transformers with the Delta Rule over Sequence Length. NeurIPS 2024. arXiv:2406.06484.
  6. T. Dao. causal-conv1d. github.com/Dao-AILab/causal-conv1d.
  7. T. Wolf et al. Transformers: State-of-the-Art Natural Language Processing. EMNLP 2020 Demos. aclanthology.org/2020.emnlp-demos.6.
  8. S. Mangrulkar et al. PEFT. github.com/huggingface/peft, 2022.
  9. J. Ansel et al. PyTorch 2: Faster Machine Learning Through Dynamic Python Bytecode Transformation and Graph Compilation. ASPLOS 2024.
  10. E. J. Hu et al. LoRA: Low-Rank Adaptation of Large Language Models. ICLR 2022. arXiv:2106.09685.
  11. F. Standhartinger and contributors. JevBench. github.com/fstandhartinger/jevbench, 2026.
  12. J. Juravsky et al. Hydragen: High-Throughput LLM Inference with Shared Prefixes. 2024. arXiv:2402.05099.
  13. L. Zheng et al. SGLang: Efficient Execution of Structured Language Model Programs. NeurIPS 2024. arXiv:2312.07104.
  14. X. Miao et al. SpecInfer: Accelerating Large Language Model Serving with Tree-based Speculative Inference and Verification. ASPLOS 2024. arXiv:2305.09781.
  15. T. Cai et al. Medusa: Simple LLM Inference Acceleration Framework with Multiple Decoding Heads. ICML 2024. arXiv:2401.10774.
  16. NVIDIA. cuBLAS/cuBLASLt (docs); CUTLASS (github.com/NVIDIA/cutlass).
  17. T. Dao. FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. ICLR 2024. arXiv:2307.08691.
  18. NVIDIA. Parallel Thread Execution ISA. docs.nvidia.com/cuda/parallel-thread-execution.
  19. NVIDIA. KDA: Kernel Development Agent. github.com/NVlabs/kda.